Agent Cost of Failure
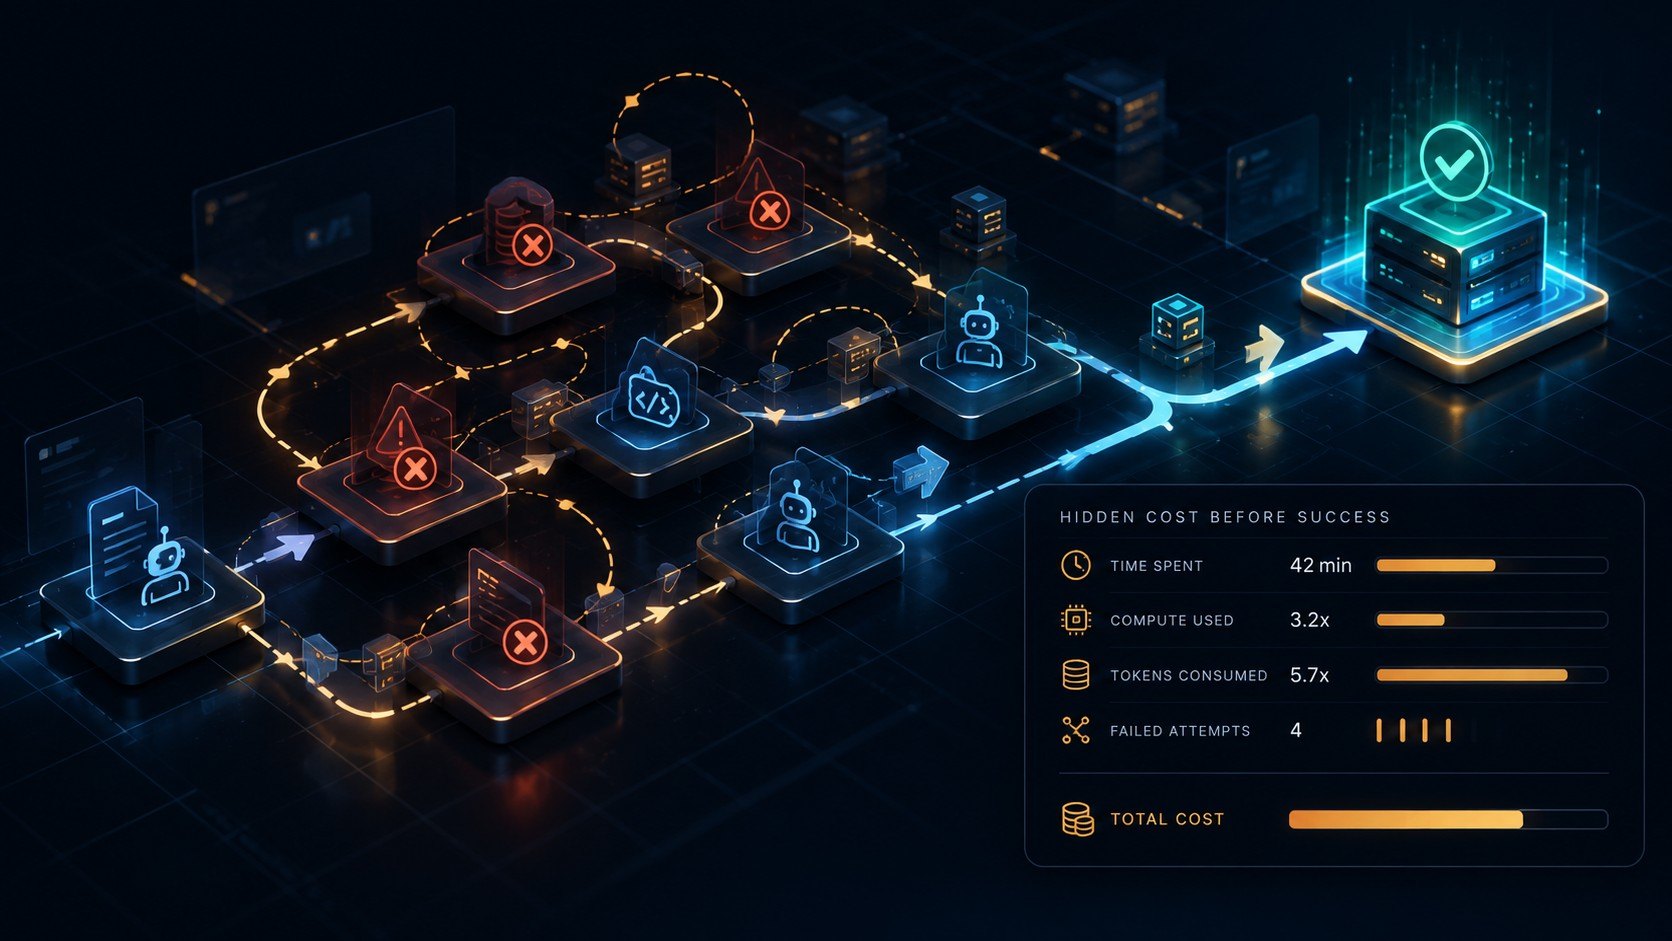
Agent Cost of Failure is the financial, computational, operational and time cost that failed attempts, retries, dead ends and unnecessary repetition added to an outcome an AI agent reports as successful.
A successful result says the job finished. It does not say what it took to get there. Agent Cost of Failure is the managerial question behind that gap: success and efficiency are different questions, and a passing outcome can hide a wasteful route.
The cost has several dimensions: money (model and cloud spend), compute (tokens, CPU and GPU time, storage and network), operations (environments rebuilt, maintenance windows used, people pulled in to check or approve) and time (the delay before the result, and to the work waiting on it).
Necessary recovery vs. avoidable waste
Not every failed attempt is waste. Some recovery is necessary: a transient network error, a dependency that was genuinely down, a safe rebuild after a failure the agent could not have prevented. Avoidable waste is the rest: repeating work that already succeeded, retrying the same failing call without changing approach, carrying context the steps never use, or rebuilding when a smaller repair would have done. Agent Cost of Failure covers both, but only the second is a target for reduction, so the measurement has to tell them apart.
Example
Consider an agent that reports a successful deployment: the service is running and all checks passed. Buried in its summary is one sentence: the first virtual machine had failed, so the agent deleted it and built another. Rebuilding may have been the safest route. But the model responses, commands, downloads, restarts and the rebuild all sit outside the green checkmark. A cloud bill may show compute, an AI provider may show tokens and a ticket may show “resolved”; none of them necessarily shows the combined cost of that one decision.
Measuring it
The number must be measured, not invented. That means connecting mission, agent, sub-agent, execution attempt, tool action, outcome, elapsed time and attributable resource usage, and classifying each failed attempt as necessary recovery or avoidable rework. In many environments the measurement will at first be incomplete, and that missing coverage should be visible too.
The cost is not always financial. A rebuild can delay another deployment, consume a scarce maintenance window or cross an authorization boundary.