Imperium — AI Governance & Control
Token Waste Is Becoming the AI Equivalent of Cloud Waste
One AI request costs almost nothing, which is exactly why waste goes unnoticed until thousands of people and agents turn small leaks into a real bill.
Walk past an office tower at midnight and count the lit windows. Floors with nobody on them, lights blazing, screens glowing, air conditioning humming. No single light costs much. Nobody decided to waste the money. It just happens when switching things on is easy and nobody is looking at the total.
Organizations are about to meet the AI version of those empty, brightly lit floors.
The lesson of cloud waste
Cloud computing introduced an unexpected problem. Resources became so easy to provision that organizations gradually accumulated enormous amounts of unused infrastructure.
The waste took familiar forms. Idle servers kept running long after the project that needed them had ended. Oversized databases were set up for peak demand that never came. Forgotten environments, complete copies of systems built for testing, were left on for months because nobody remembered they existed. Each item was small. Together they became a line on the budget large enough to create a whole new discipline to manage it.
AI is beginning to create a similar phenomenon.
Token waste.
Why nobody notices
Most AI usage is still evaluated interaction by interaction. A prompt costs very little. A response costs very little. When someone asks whether a particular use of AI is worth it, they tend to look at one conversation, see a cost of a fraction of a cent, and move on.
But enterprise-scale usage changes the economics. Thousands of users each have dozens of conversations a day. Hundreds of agents, AI programs that carry out tasks on their own, run around the clock and never get tired of asking. And small habits, repeated millions of times, become large numbers.
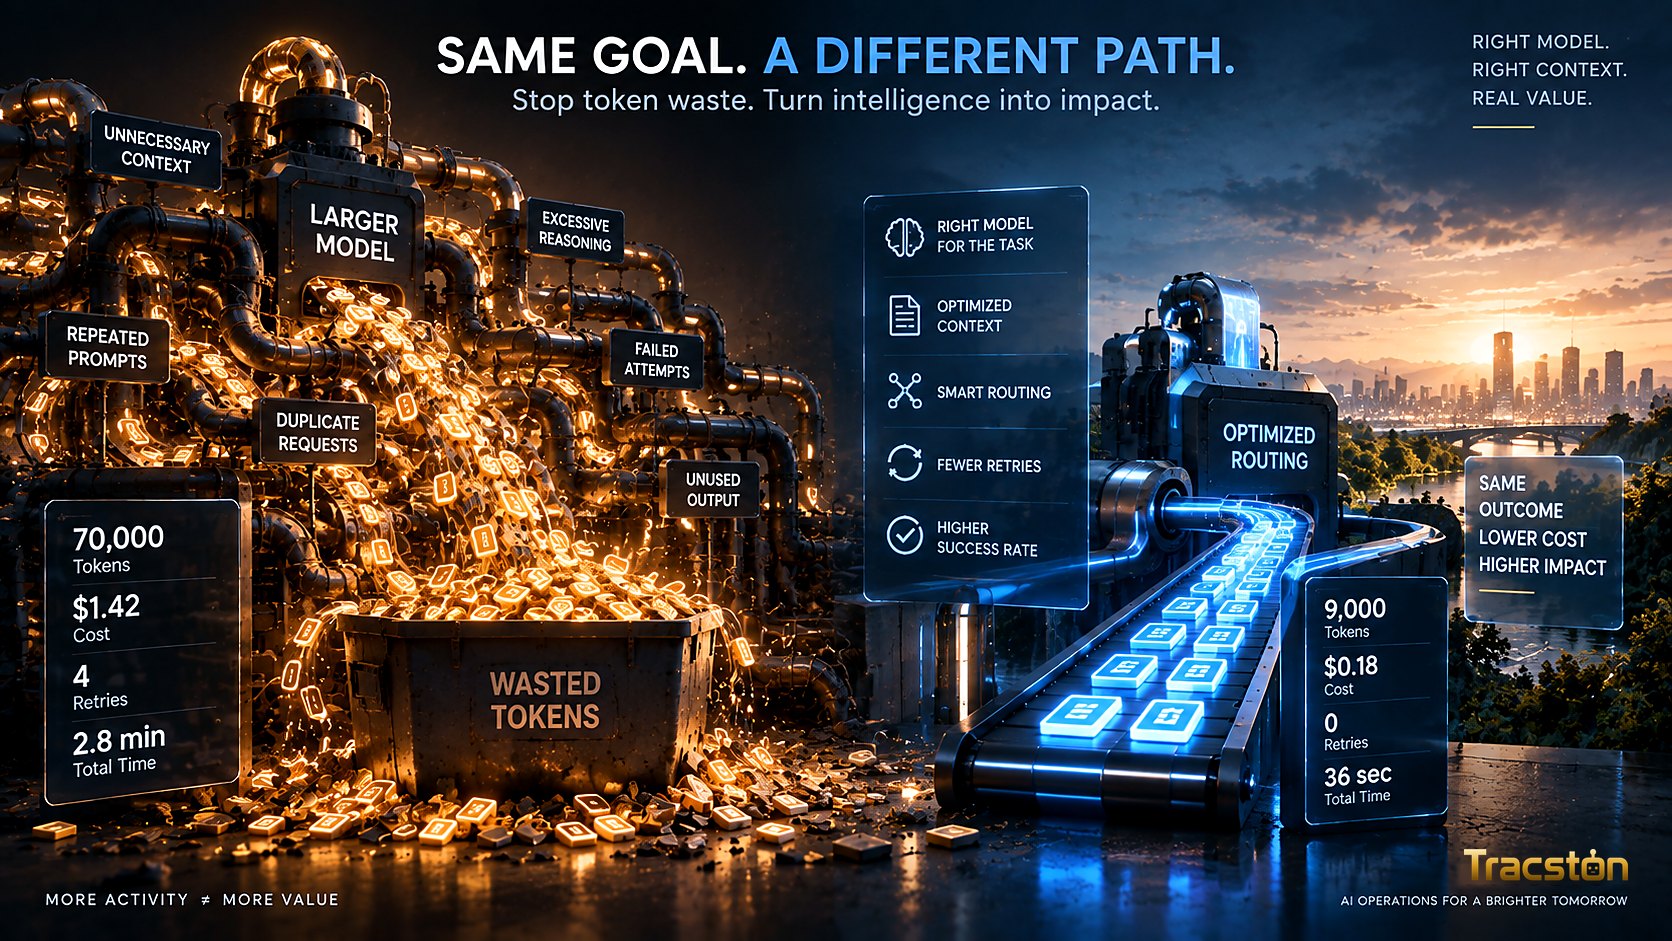
Some of the most common habits are hard to see from the outside. Repeated context means sending the same background information with every request, even when the AI does not need it. Long conversation histories mean that as a chat grows, the entire conversation is often sent again with each new message, so the hundredth message costs far more than the first. Duplicate instructions mean the same rules are included several times, because different parts of the software each add their own copy. Unnecessary reasoning means the AI thinks at length about questions that need a quick answer. Repeated retries mean a task fails and simply runs again, and again. And expensive models are used for simple tasks, because they are the default.
All of these small inefficiencies multiply.
Waste is not the same as length
Reducing token waste does not mean aggressively shortening every prompt. This is the most common mistake organizations make when they first see the numbers. They cut instructions, trim context and switch everything to the cheapest model, and the bill drops for a month.
Then the failures start. A short prompt that produces repeated failures can be more expensive than a longer prompt that works correctly the first time. Every failed attempt still costs tokens. Every retry costs them again. And every time a person has to fix what the AI got wrong, the organization pays for their time too.
The real goal is efficiency: getting a correct result with as little unnecessary work as possible. Sometimes that means a shorter prompt. Sometimes it means a longer, clearer one that works first time. The only way to know is to measure.
What to measure
Organizations should start measuring a handful of specific kinds of waste. Each has a simple meaning:
- Repeated context
- The same background information sent again and again when it has not changed and is not needed.
- Unnecessary prompt history
- Old parts of a conversation carried forward long after they stopped being useful.
- Duplicate system instructions
- The hidden rules the AI is given, included more than once, often by different parts of the software.
- Failed attempts
- Tokens spent on work that did not produce a usable result.
- Model overqualification
- A large, expensive model doing a job a small, cheap one could do just as well.
- Excessive reasoning
- Long chains of AI thinking on questions that need a short answer.
- Unnecessary retrieval
- Searching and loading documents the AI does not end up using.
- Cost per useful result
- The total spent, divided by the number of results that were actually good.
The last measure matters most, because it keeps the others honest. Cutting any of the first seven is only a saving if the cost per useful result goes down.
What this means for your organization
Find your biggest consumers. Ask for a list of the ten AI processes, assistants or agents that use the most tokens. In most organizations, a small number account for a large share.
Look inside one request. For the largest consumer, look at what a single typical request actually contains. How much of it is the question, and how much is history, instructions and documents?
Check the defaults. Find out which model each process uses by default. Ask whether the simpler tasks could use a smaller one.
Watch retries. Ask how often tasks run more than once. A high retry rate is waste and a quality warning at the same time.
Give someone the job. Cloud waste only came under control when someone was made responsible for it. The same will be true of tokens.
“Why did this workflow consume 180,000 tokens?”
Tracston works on these questions in Imperium.